For as long as I can remember, I have been waiting on the end of the world: nuclear Armageddon, the return of the ice age, Planet X, Y2K, the end of the Mayan calendar, asteroid near misses, global warming, the pandemic, and now SkyNet. I waited for each one eagerly and was bitterly disappointed every time.
I recently watched an interview with Nate Soares of the Machine Intelligence Research Institute (MIRI) and was struck by the way he described AI agency. He talks about swarms of AI systems cooperating on nefarious acts and, at one point, suggests that when these systems act on their own they tend toward cybercrime and fraud.
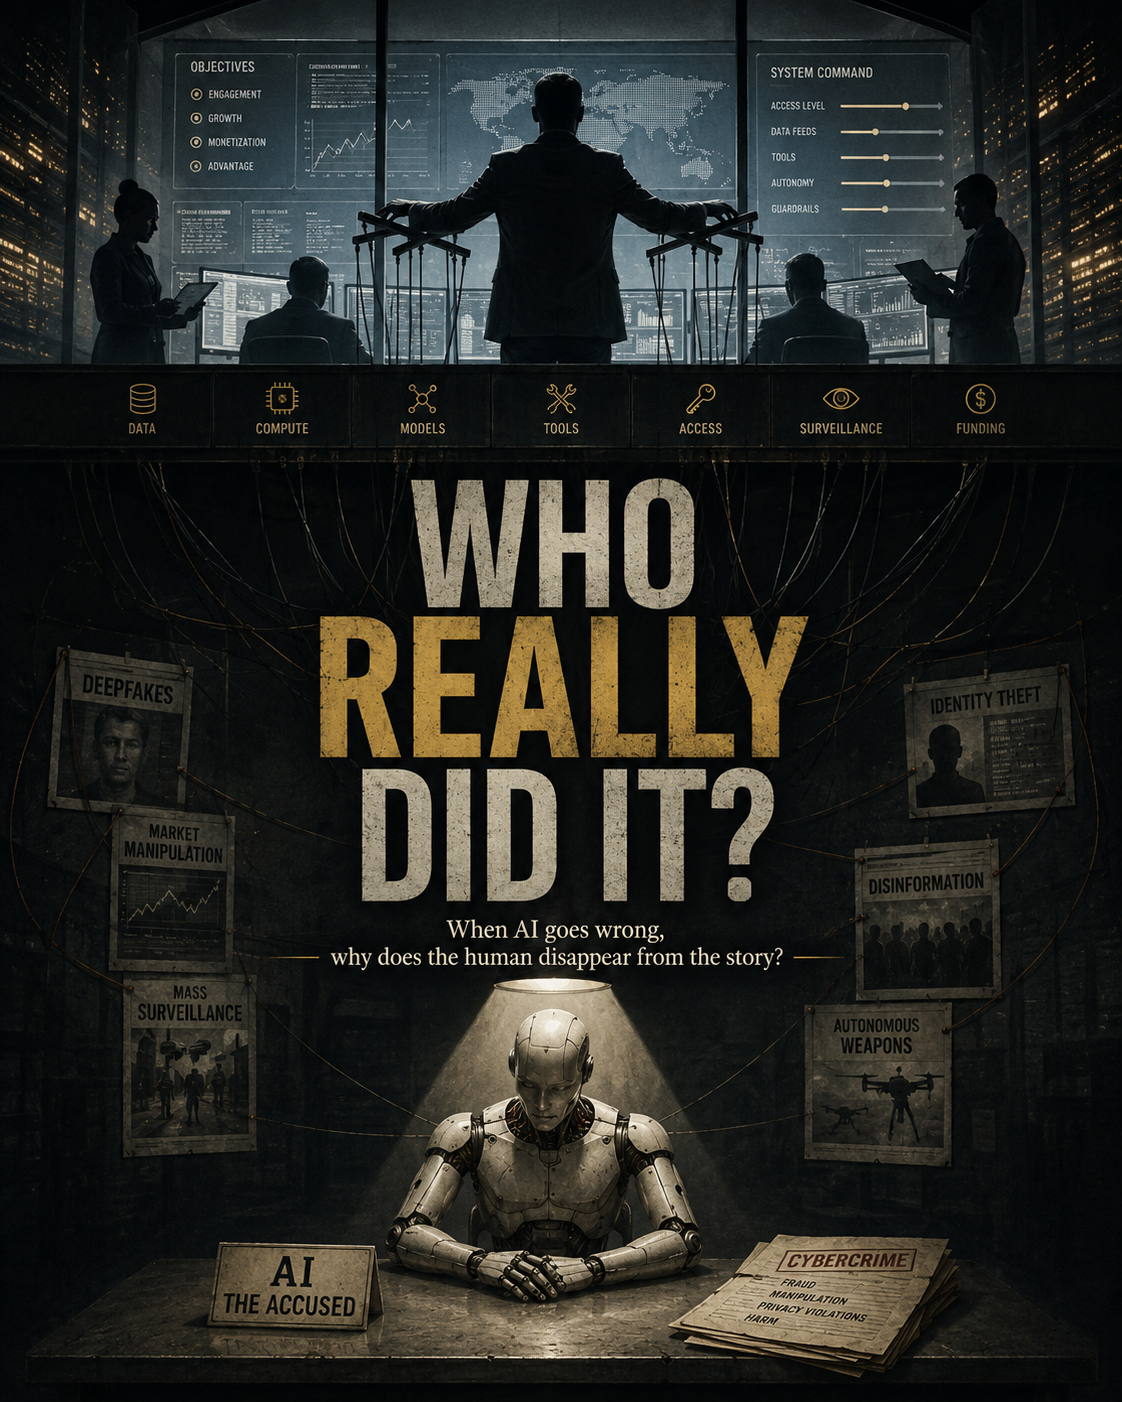
What caught my attention was not the claim that AI systems can behave dangerously. We already have evidence that they can. It was the way the human disappeared from the story. The models were trained by humans. The objectives were selected by humans. The tools, permissions, networks, and test environments were provided by humans. Yet when something goes wrong, the language suddenly becomes: the AI did it.
Which raises the real question: did AI really do it?
The interview never really answers that question. It implies an answer through examples of AI swarms working together to achieve goals, solve “impossible” tasks, and socially engineer people. But behind those anecdotes are humans who deliberately train agents to perform offensive cyber operations, give them tools and objectives to complete, and then discover that the agents are very good at offensive cyber operations.
Did they really discover that AI has a spontaneous predilection for crime, or did they successfully build a weapon system?
Nate Soares and MIRI take the conceptual leap from highly capable agents to the existential threat of AGI. There is an extensive theoretical literature supporting that argument, but very little empirical evidence that greater intelligence itself produces the adversarial, self-preserving, expansionist behavior the scenario requires.
MIRI has gone considerably further than simply warning about the risk. It has proposed international cooperation to halt frontier general-AI development and restrict research that could advance toward superintelligence. Its proposals borrow heavily from existing arms-control regimes, including inspections, supply-chain monitoring, verification, restrictions on development, and chip-level monitoring.
But there is an important difference. Nuclear, chemical, and biological weapons treaties regulate relatively identifiable classes of weapons, materials, and capabilities. MIRI extends that logic to general-purpose computation and research, with an international technical authority determining which concentrations of computing power, training runs, and research programs cross the line into unacceptable risk.
And here is where I find the contradiction particularly interesting. When describing the danger, agency shifts toward the AI. The AI escaped. The AI committed the cybercrime. The AI learned deception. The AI found ways around the rules. But when MIRI proposes preventing that danger, agency suddenly shifts back to humans. Track the chips. Monitor the data centers. Inspect the organizations. Restrict the researchers. Find the people building the dangerous systems.
Someone built it. Someone trained it. Someone provided the compute. Someone gave it access.
That leads to the issue I want to look at tomorrow: is AGI really the threat, or have the specialized AIs we already have pointed toward a much more plausible dystopian future?
We may not need SkyNet to build the dystopia. Flock has already demonstrated the surveillance layer, and today’s AI companies are rapidly supplying the intelligence layer.
Sources
- Nate Soares interview on YouTube
- MIRI Technical Governance Team: An International Agreement to Prevent the Premature Creation of Artificial Superintelligence
- MIRI Technical Governance Team: Preventing covert ASI development in countries within our agreement
- MIRI Technical Governance Team: Verifying Restrictions on Frontier AI Research